Even if your AI PoC or pilot handles demo questions well, it can perform much worse with real documents, real users, and a distributed, inconsistent company knowledge base.
It doesn’t necessarily mean that AI models are degrading. More likely, they’re just struggling to find the right information when someone asks.
Context engineering is how software development teams make AI outputs hold up in production. In this article, we look at context engineering, a key part of AI development, outline the most common mistakes, and share practical tips for getting it right.
What Is Context Engineering in AI Development?
Context engineering decides what your AI sees before it answers. That covers:
The instructions it follows
The documents it pulls from
The tools it can use
The conversation so far
The facts about the person asking
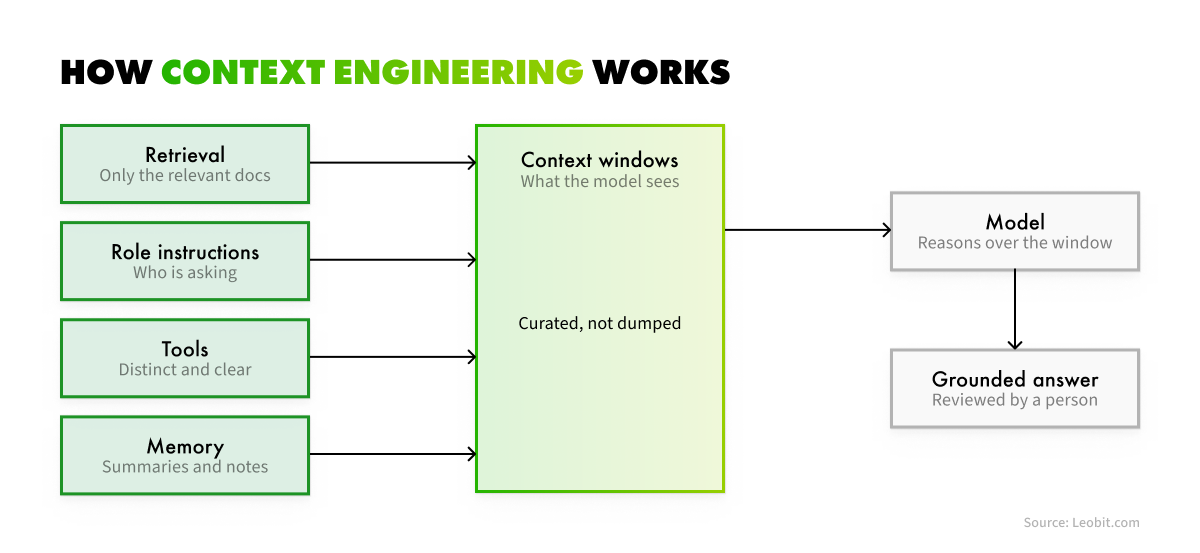
It also covers what the AI does when the answer isn’t in your data. Think of it as briefing a new hire. Get the briefing right, and the AI gives answers you can trust. The image below illustrates the key principles of context engineering.
Context engineering workflow
Context engineering vs. prompt engineering is a common point of confusion, yet the two do different jobs, and both affect the quality of AI outputs. Prompt engineering is how you structure and word an instruction. Context engineering is everything else the AI sees when it answers, and that is where many real-world problems start.
The practical difference comes down to the question each one asks. Prompt engineering asks how to phrase the request. Context engineering asks four questions:
Which documents from the knowledge base should accompany a request?
What the assistant should know about the person asking?
Which tools it can use?
What it should remember?
These questions are essential, and each deserves careful attention.
What does the model retrieve?
Retrieval-augmented generation (RAG) pulls relevant documents into the context at query time instead of pre-loading everything. The approach you pick depends on how your data is shaped.
Graph RAG suits interrelated datasets where relationships carry meaning
Hybrid search suits data where exact terms matter as much as meaning, such as product codes, regulation numbers, or names
Multi-hop retrieval helps when an answer depends on several steps of reasoning, with each document leading to the next
However, many projects need none of these specialized setups. Semantic search over a well-curated knowledge base, which finds documents by meaning rather than exact wording, is often enough.
It’s worth mentioning ine-tuning is an alternative to RAG, and the two approaches should not be confused. It retrains the model on your data and changes the model itself, while RAG leaves the model unchanged and supplies context at query time.
Mykola Sheredko
Solutions AI Architect at Leobit
For example, the intelligent shipping orchestration platform the Leobit team built for a Swedish logistics company takes this approach. The client’s employees use it to ask questions on national and international logistics regulations in plain language. The solution’s RAG workflows retrieve relevant regulations from a curated knowledge base and use GPT-based models, orchestrated through LangChain, to generate accurate and context-specific answers. A vector database supports semantic search to ensure that responses are always grounded in reliable sources.
As a result, the client’s employees get a dependable way to check the rules before they act. That helps the company avoid costly violations and the delays, fines, and rework that follow.
Who is the intended recipient of the model’s answer?
A single document carries different meanings for different readers. A contract clause that matters to a compliance officer may matter little to someone in operations. That is why context engineering has to start with the people using the system: who they are and what they need from each answer.
We applied this to a contract management platform for a Swedish automotive enterprise. Each user role gets its own prompt template, so legal, compliance, and operational teams receive explanations tailored to their concerns.
This makes the solution more convenient because each person gets the answer they need, in a form they can act on right away.
What tools can a model call?
Agents act through tools, and every tool definition takes up space in the model’s context. To handle tool calling effectively, Anthropic recommends keeping tools clear and distinct, with minimal functional overlap. If a human engineer can’t say which tool fits a situation, an agent won’t choose well either.
Consider a hypothetical AI-powered support agent equipped with two tools that search the same documentation, differing only in how their descriptions are worded. When a customer submits a question, the agent has no clear basis for preferring one tool over the other, so its choice is inconsistent and responses may vary between requests. While working on context engineering for AI agents, the team can consolidate the two tools into a single, clearly described tool to remove this ambiguity. The agent knows where to look, and the team has one tool to test and maintain.
Long-running tasks can exhaust even the largest context window, so AI systems need a way to carry forward what matters. Anthropic describes three techniques for this:
Compaction summarizes the conversation as it nears the limit, preserving key decisions and dropping redundant output.
Structured note-taking moves progress into external storage, which the agent reloads whenever it needs it.
In agentic AI setups, sub-agent architectures split the work among specialized agents, each with a clean context window that returns only a short summary of its findings to the lead agent.
Leobit largely relies on the second approach in our AI-native SDLC. Requirements live in version-controlled specifications, architecture documents, and memory files, so shared context follows the code instead of sitting in one engineer’s chat history. The AI Engineering Kit reads and writes that context, and every change a human reviewer accepts goes back in as knowledge the team can reuse.
For clients, this means projects keep their momentum when team members change, while new engineers get up to speed faster.
Four Ways Business AI Projects Get Context Engineering Wrong
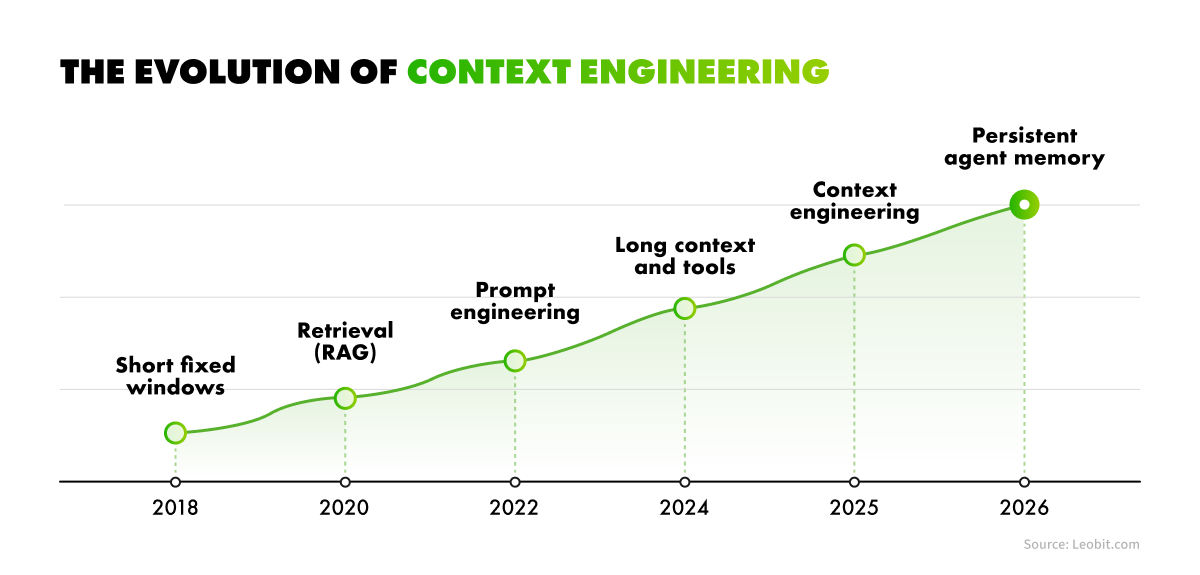
Context engineering has evolved significantly within last 8 years. But some issues with output accuract persist.
The evolution of context engineering
Even well-resourced AI initiatives often falter on context engineering. These are the four mistakes we see most often in real projects, and each one is avoidable.
Loading everything, just in case
Development teams often feel compelled to give the model all available information. This approach is counterproductive because it can lead to context rot. As the amount of text grows, models recall specific details less reliably. Anthropic reports that this affects all models, and larger context windows are unlikely to remove it.
Larger inputs also slow responses and raise costs, and extensive datasets are harder to structure and maintain. They often contain outdated or conflicting material, leaving the model unable to determine which source is correct. A carefully curated knowledge base performs better. It gives the model a clear path to the relevant information and removes contradictions before they reach the answer.
Treating the knowledge base as finished
Your company updates policies, retires products, revises pricing, and rewrites documentation. An AI assistant that draws on a knowledge base nobody updates will keep citing the old version. It will do so with the same confidence as before, providing false information to both employees and customers.
Freshness needs an owner. Assign a named person or team to the knowledge base, and set a documented review cycle that says what gets checked, how often, and who signs off. Tie it to the events that make content outdated, such as a policy update or a product launch, so changes reach the assistant when they happen.
Removing the human too early
Strong test results tempt teams to cut human review and let the system run on its own. Unfortunately, accuracy measured in testing rarely survives contact with real-world conditions. When errors do slip through, nobody is accountable for catching them, and nobody learns from them.
To avoid this problem, keep human review in place, especially for high-stakes decisions. Have reviewers confirm or correct the AI’s output, and log every correction. Those corrections show where the system fails and give you the best data for improving it.
Measuring the model instead of the workflow
Accuracy benchmarks are easy to collect, so teams often treat them as proof of success. They rarely answer the question leadership actually asks: what changed for the business? A model can score well in testing and still leave the underlying process slow, costly, or unchanged.
Measure the workflow instead of tracking the model’s accuracy rate. Before launch, record how long the task takes today, how often it goes wrong, and what each error costs. After launch, track the same figures and compare. Metrics such as time per task, error rates, rework, and cost per case indicate whether the system delivers a return on investment. Model scores reflect how well the AI performs, while workflow data shows whether the business benefits.
How to Get Started with Context Engineering
To start context engineering, you need one workflow and an honest look at how it runs. Here’s a step-by-step guide built on context engineering best practices:
Pick a workflow where people repeatedly look things up. Start where the pain is obvious: staff who search the same sources every day to answer the same kinds of questions. Customs rules, contract clauses, internal policies, and product specifications are strong candidates. A narrow, frequent task also gives you a clear before-and-after comparison.
Map the sources your team actually uses. Skip the official list and write down the real one, including the spreadsheet somebody maintains privately and the folder everyone knows about but nobody has yet documented. These informal sources often hold the answers people trust most, and your AI needs to see them.
Build a small retrieval set and test it on real questions. Collect the questions your staff asked last week and run them through the system. Real questions expose gaps, vague wording, and missing documents that synthetic test sets miss. Get retrieval right before you change anything else.
Add role-specific instructions. Once retrieval returns the right material consistently, tailor the answers to each user group.
Keep a person in the loop, and log every change. Reviewers confirm or fix the AI’s answers, which keeps someone accountable for the result. Each correction also shows where the system fails and gives you concrete data for improving it.
A reliable way to determine whether everything is working is an AI-powered proof of concept. By the end of such an experiment, you know whether the workflow is worth automating, and you know it before you commit to a platform.
How Leobit Can Help Your AI Pilots Succeed with Context Engineering
Every AI transformation project brings its own requirements and obstacles, much as every organization’s knowledge base is different. Handling that variety takes AI expertise, and that is where Leobit can help. Leobit has worked with AI for six years and delivered more than 40 AI projects for companies across industries. Our team keeps deepening that expertise, and we are a Microsoft Solutions Partner for Digital & App Innovation and Data & AI. We also recently became Certified in the Claude Partner Network, Anthropic’s program for partner organizations helping enterprises adopt Claude.
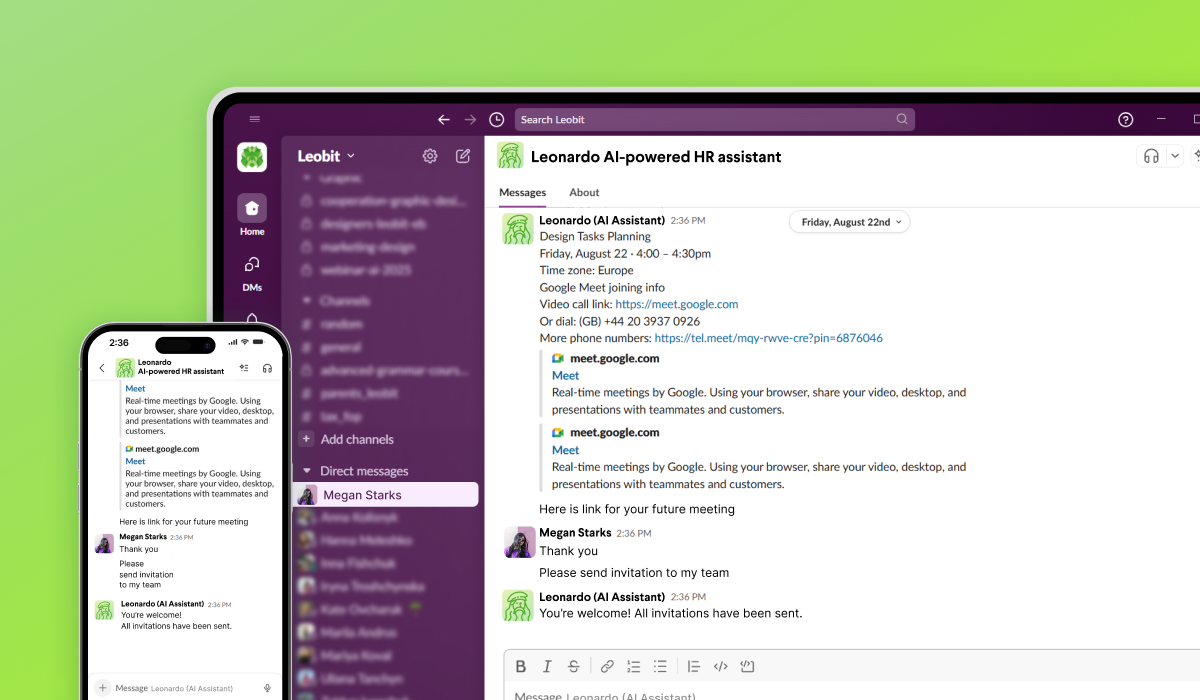
We also test our approach to context engineering on our own products first. Leora, our voice sales assistant, and Leonardo, our internal HR assistant, run on curated knowledge bases with retrieval that our engineers tuned and reviewed. The same discipline shapes our AI-Native SDLC, where specifications, architecture documents, and memory files give agents shared context, and a human approves every plan, specification and entry in the shared knowledge base.
Our services also cover custom LLM and knowledge base development, RAG architecture design, and a PoC that proves the workflow before you commit to a platform.
Final Thoughts
The AI pilots that make it into production rarely win on model choice. They get there because somebody decided what the system could see, who reviewed its answers, and what would count as proof that it worked.
That makes context engineering fundamental for your AI project’s success. Retrieval design, role-specific instructions, tool definitions, and memory each need a named owner and a review cycle, because each one goes stale on its own schedule. A knowledge base nobody maintains will quietly undo months of good engineering.
Pick one workflow and instrument what the model actually receives on real questions, with a reviewer in the loop while the system earns trust. Measure the workflow rather than the model. Teams that work this way usually end up with fewer AI systems than they planned, and more that people keep using.
If you need help organizing your company’s knowledge base, setting up a continuous context engineering workflow, or building a custom AI solution grounded in your own data, Leobit can help. Contact us to discuss your needs and put AI to work in a way that fits your business.
FAQ
No. Models recall specific details less reliably as the amount of text grows, a pattern known as context rot, and Anthropic reports that it affects all models regardless of window size. Larger windows give you more room for the information that matters. Deciding what that information is remains the work, and filling the window with marginally relevant material negatively impacts the quality of the outputs.
Prompt engineering is how you word an instruction. Context engineering is everything else the model sees when it answers: retrieved documents, tool definitions, the conversation so far, and what the system knows about the person asking. Prompt engineering is one component of context engineering, and in production systems it is rarely the component that decides output quality.
Not all of it. Curate the slice that one workflow depends on, then test retrieval on real questions your staff asked recently. A narrow, well-maintained source can perform better than a complete one full of outdated and conflicting documents.
Measure the workflow rather than the model. Record how long the task takes today, how often it goes wrong, and what each error costs, then track the same figures after launch. Time per task, error rates, rework, and cost per case show whether the system pays off. Accuracy benchmarks describe the model and say little about the business result.
Leobit provides experienced software engineers who build the retrieval pipelines, memory, tool integrations, and evaluation setups that give language models the right context for each task. We work with Azure OpenAI and Claude, and we apply the same practices in our own AI-native SDLC. As a result, your AI answers stay grounded in your own up-to-date data, with a person reviewing them where the stakes are high.
Mykola Sheredko is a Solutions AI Architect leading AI Enablement at Leobit, helping teams and clients bring AI into everyday software development while keeping quality and people at the center. Anthropic-certified, he has worked across healthcare, fintech, and govtech, from modernizing legacy systems to building products from scratch. Mykola is focused on making AI practical and reliable beyond demos.
Roman has a deep passion for a wide array of subjects, spanning from market insights to in-depth technical examinations of complex projects. He dives deep into technical aspects of various solutions to extract valuable insights for business purposes, and he enjoys sharing tips and tricks with business owners to help them leverage advanced technologies effectively.
MIT’s State of AI in Business 2025 report shows that monthly job listings for forward deployed engineers increased by more than 800% this year, part of a ...
The .NET ecosystem continues to flourish in 2026, with over 478,000 packages on NuGet that have been downloaded over 800 billion times. Numbers from ...
This year’s studies suggest that 31% of organizations across Norway, Sweden, Denmark, and Finland plan to increase spending on external IT service providers ...
Leona, Leobit’s AI agent designed to find promising cooperation opportunities and automatically send requests for proposals (RFPs), has helped our sales ...
Gartner estimates that generative AI cost projections can be off by 500% to 1,000% when organizations fail to account for how costs scale. They also predict ...
A 2025 DORA survey found that 90% of software engineers now use AI in their daily work. These numbers show that AI adoption has become a universal standard in ...
AI features rarely fail during a demo. They usually fail a few months after launch, when finance asks why the AI assistant is costing far more than anyone ...
17 mins read
We use cookies to enhance your browsing experience. By agreeing, you accept our Privacy and Cookies Policy.
By ignoring or closing this banner, we will only collect essential cookies necessary for the website to function properly.
 Leobit